Search and copy from a scan
After OCR, the words on a scanned page are stored in a text layer. You can find a phrase with the search box in your PDF reader, select a line and copy it into another document.
or drop a file anywhere here
Files other than PDF are converted first. Signing in raises the size limit.
Running OCR on a PDF turns the picture of each scanned page into text you can search, select and copy. OCR stands for optical character recognition. This tool reads a PDF and returns a PDF in which image-only pages carry a text layer. You tick the languages the document is written in: English, German, French, Portuguese or Chinese (Simplified). Pages that already contain text are left as they are. The result is always a PDF. To get an editable document, run OCR here first and then convert the searchable PDF to Word.
After OCR, the words on a scanned page are stored in a text layer. You can find a phrase with the search box in your PDF reader, select a line and copy it into another document.
The Document languages list has five boxes: English, German, French, Portuguese and Chinese (Simplified). English is ticked when the options appear. Tick every language used in the document and leave the others clear, because more languages means slower OCR.
The job skips any page that already holds text and works on the image-only pages. A file that mixes typed pages with scanned inserts comes back with the typed pages as they were.
A converter can only export text that exists in the file. Give a scan its text layer here, then pass the searchable PDF to the PDF to Word page.
| Your scan has | Tick | Good to know |
|---|---|---|
| Text in English | English | It is ticked when the options open. |
| Text in one other language, such as German, French, Portuguese or Chinese (Simplified) | That language | Clear English if no page uses it. |
| Pages that mix two languages | Both languages | The choices are passed to the OCR engine together, so one page can be read in both. |
| A language that is not in the list | Nothing to tick | The list holds the five languages the OCR engine ships with. Use another OCR program for other languages. |
Drag the scan onto the upload box, or click the box and pick the file.
Under Document languages, tick each language used in the scan. English is already selected.
Press Run OCR PDF and let the progress bar reach the end. Download the file and try selecting a word to confirm the text layer is there.
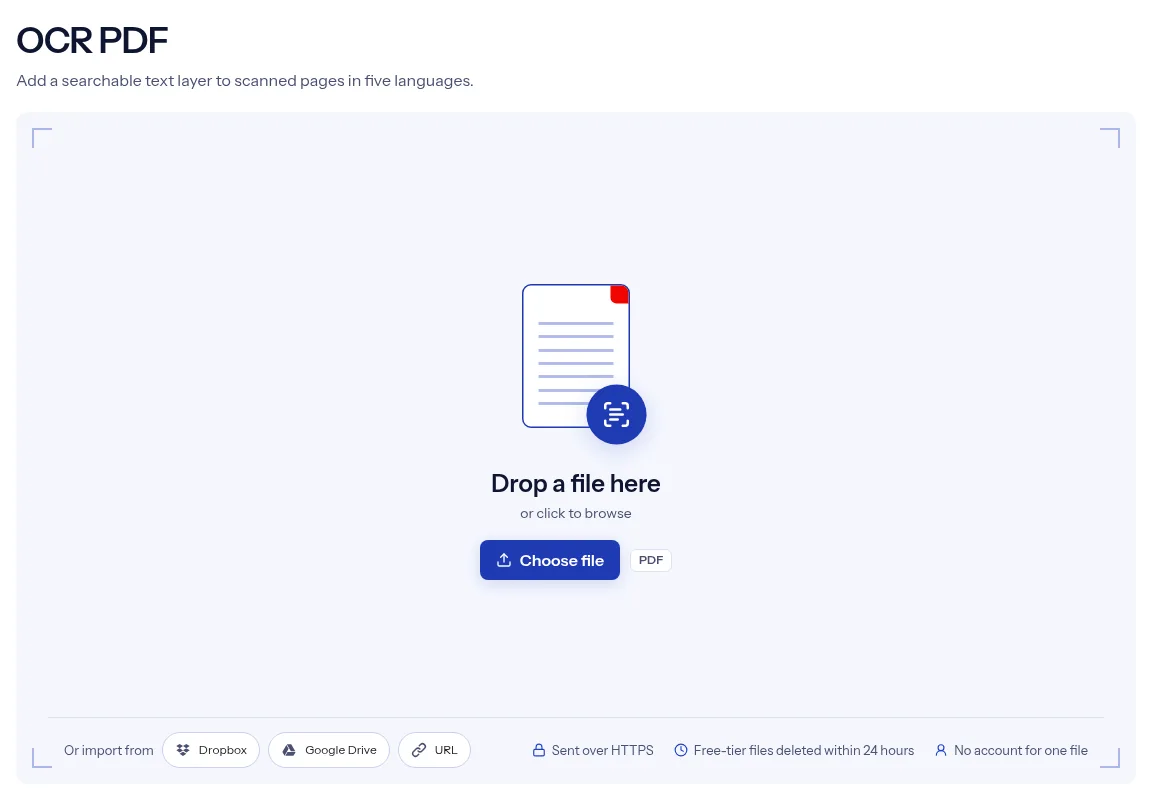
You see what the job will do before you start. There is one choice to make, the language list, and the rest is fixed: scanned pages get a text layer, pages with text stay as they were, and you receive a PDF. A single scan runs without an account. Your upload is sent over HTTPS when you press Run, and free-tier files are removed automatically within 24 hours after the job finishes. The page is also direct about what OCR cannot do here. It reads five languages, it will not redo an existing text layer, and it does not check its own accuracy. That lets you judge whether the tool fits your scan before you upload anything.
| What you see | Why | What to do |
|---|---|---|
| Nothing is searchable after the run | The pages already had text and were skipped, or the OCR step failed and the job returned your PDF as it was | Search for a word from a scanned page. If nothing is found, run the job again. A page that already has a wrong text layer stays as it is. |
| Words come out garbled | The scan is low resolution, tilted or faint, or the page is in a language you did not tick | Rescan at a higher resolution, straighten the page and tick every language in the document. Tesseract works best on images of at least 300 dpi. |
| Sideways pages read as nonsense | The form has no rotate setting | Turn the pages upright with Rotate PDF, then run OCR again. |
| The signature shows as invalid | OCR rewrites the file, and a rewritten file cannot keep its digital signature | Keep the signed original as the record and use the OCR copy only for searching. |
| The job cannot open the file | The PDF asks for a password and the form has no place to type one | Remove the password with Unlock PDF, then run OCR on the open copy. |
Signed contracts and letters come off the scanner as pictures. OCR lets you search them for a name, a date or a clause.
A scanned chapter or journal article cannot be searched or quoted. With a text layer you can find a term and copy a passage into your notes.
Scanned invoices and receipts are hard to look up later. After OCR you can search each file for an invoice number or a supplier name.
Facts checked on October 16, 2026
No tool matches that search.
It reads the letters on each scanned page and adds them as a text layer. The page keeps its picture, and you can now search, select and copy the words.
English, German, French, Portuguese and Chinese (Simplified). Tick each one that appears in your document.
No. The language field warns that more languages means slower OCR, so tick only the ones your document uses.
The job falls back to English.
No. Pages that already contain text are skipped, and only image-only pages are processed.
This tool returns a PDF. Run OCR first, then convert the result on the PDF to Word page.
Open the download and try to select a word or search for one. If nothing can be selected, the OCR step most likely did not run and the job returned your original, so run it again.
No. A single job works without an account, and signing in or moving to a paid plan raises the limits.